AI crawler access
AI Crawler Policy Template for Public Service-Business Websites
A crawler policy should not be copied from a technical forum and pasted into robots.txt. For a public service business, it should explain which pages are meant to be found, which areas are low value, which material must be protected, and who reviews the rule when the website changes.
Direct answer: what should an AI crawler policy include?
An AI crawler policy should list public pages that may be crawled, private areas that need authentication, low-value paths to limit, crawler-specific rules for OAI-SearchBot and GPTBot, CDN or firewall exceptions, owner responsibilities, and a review cadence. Treat robots.txt as one control, not the whole policy.
If your website sells accounting, legal, consulting, HVAC, dental, agency, or other professional services, your public pages are business assets. You want buyers and search systems to understand your services. At the same time, you do not want client files, test pages, old PDFs, forms, portals, or checkout-style paths exposed just because they live on the same domain.
This is where a policy template helps. The earlier guide on whether small businesses should allow AI crawlers covers the business decision. The AI crawler robots.txt audit shows how to inspect the technical setup. This article gives you the operating document: a simple template your owner, marketer, web partner, and IT support can actually use.
For crawler and AI search topics, the practical next step is an AI Search Visibility Audit. It checks crawl access, page clarity, internal links, evidence, schema, and whether public pages are strong enough to be cited or recommended in AI search.
Why a policy is better than a one-line rule
A one-line robots.txt rule answers only one technical question: should a named crawler fetch a path? A service business has a broader question: what are we comfortable making available, and what do we want to be discovered for?
OpenAI's crawler documentation separates OAI-SearchBot, GPTBot, OAI-AdsBot, and ChatGPT-User. The important business point is that search visibility and training access can be managed separately. A company may allow OAI-SearchBot for ChatGPT search visibility while making a different decision about GPTBot. That distinction should be written down.
Google's robots.txt documentation is also clear that robots.txt is not a privacy or access-control mechanism. It manages crawler access. If a page must stay private, use login protection, remove it from public URLs, or publish a safer public version. Do not leave sensitive files public and hope every automated system behaves the way you expect.
A good policy gives your web partner something concrete to implement and review. It also protects you from accidental changes. When a new landing page, resource library, client portal, or lead magnet goes live, someone can ask: which policy group does this page belong to?
The AI crawler policy template
Use this as a working template. It is not legal advice and it is not a universal robots.txt file. It is a practical policy structure for public service-business websites.
1. Business goal
State the reason for the policy in plain language.
- We want public buyer pages to be discoverable in search and AI search.
- We do not want private, gated, client-specific, or operational material to be crawled.
- We want training crawler access to be an explicit business decision.
2. Page groups
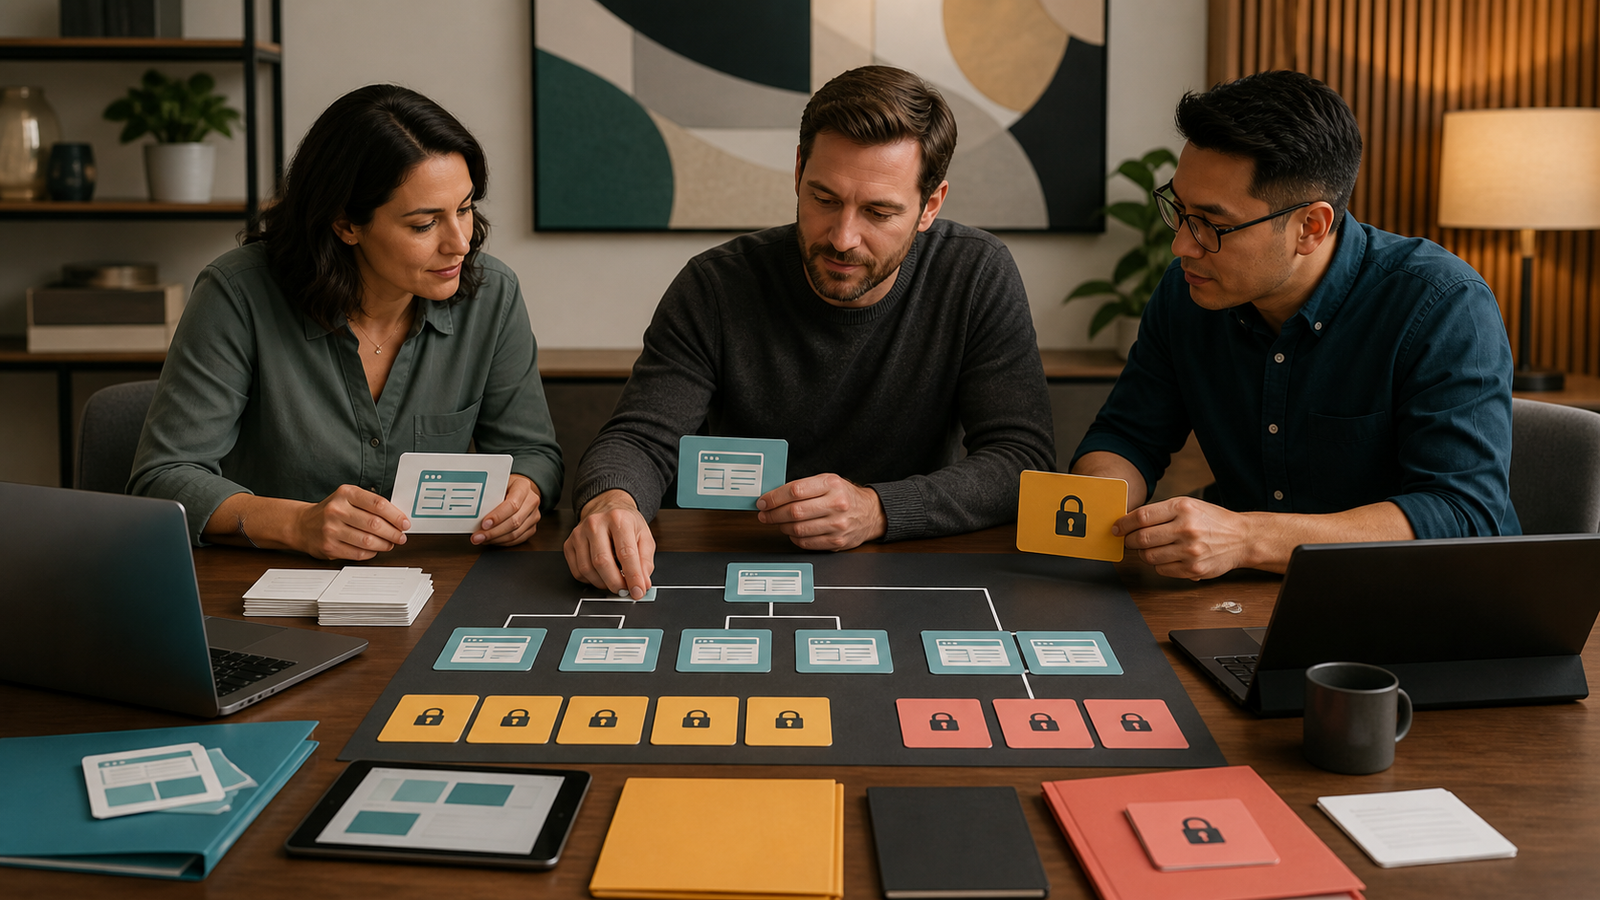
Group URLs by business purpose before writing crawler rules.
- Public allow: homepage, service pages, industry pages, location pages, guides, blog articles, FAQ pages, about page, contact page, and public case-study style pages.
- Limit or block: internal search results, tag archives, admin paths, duplicate filtered pages, cart or checkout paths, test pages, staging paths, and thin attachment pages.
- Protect with authentication: client portals, proposals, invoices, contracts, intake notes, internal SOPs, private downloads, and non-public PDFs.
- Review before publishing: lead magnets, reports, pricing pages, public calculators, downloadable templates, and pages with customer-specific examples.
3. Crawler-specific decision
Separate crawler roles. Do not treat every bot name as the same business risk.
- OAI-SearchBot: usually allow for public pages if ChatGPT search visibility matters.
- GPTBot: decide separately because it relates to training use, not just search visibility.
- Googlebot: do not block unless you intentionally want to affect Google Search crawling.
- Unknown or aggressive crawlers: monitor through hosting, CDN, or security tools instead of guessing from robots.txt alone.
4. Owner and review cadence
Name the person or role responsible for policy changes. For most SMBs, this should involve the owner or operator, the website partner, and whoever manages security or hosting. Review it quarterly and whenever a new portal, resource library, or website section goes live.
Starter robots.txt pattern for a public service website
The rule below is a discussion starter, not something to paste blindly. Your site structure, CMS, forms, hosting, and risk tolerance matter. Still, it shows the useful split: public search crawling can be allowed while training crawler access is a separate decision.
User-agent: OAI-SearchBot
Allow: /

User-agent: GPTBot
Disallow: /

User-agent: Googlebot
Allow: /

User-agent: *
Disallow: /wp-admin/
Disallow: /account/
Disallow: /checkout/
Disallow: /cart/
Disallow: /search/

Sitemap: https://example.com/sitemap.xml
For a WordPress service-business site, keep the rule simple unless there is a reason to add complexity. Blocking every tag or category page may be useful on one site and unnecessary on another. Blocking public service pages is usually a mistake if those pages are meant to bring qualified buyers into the business.
OpenAI also notes that web protection, bot mitigation, CAPTCHAs, JavaScript challenges, and rate limits can block crawler access even when robots.txt looks correct. That is why the policy should include CDN and firewall checks, not just the robots file.
Decision table: what to allow, limit, or protect
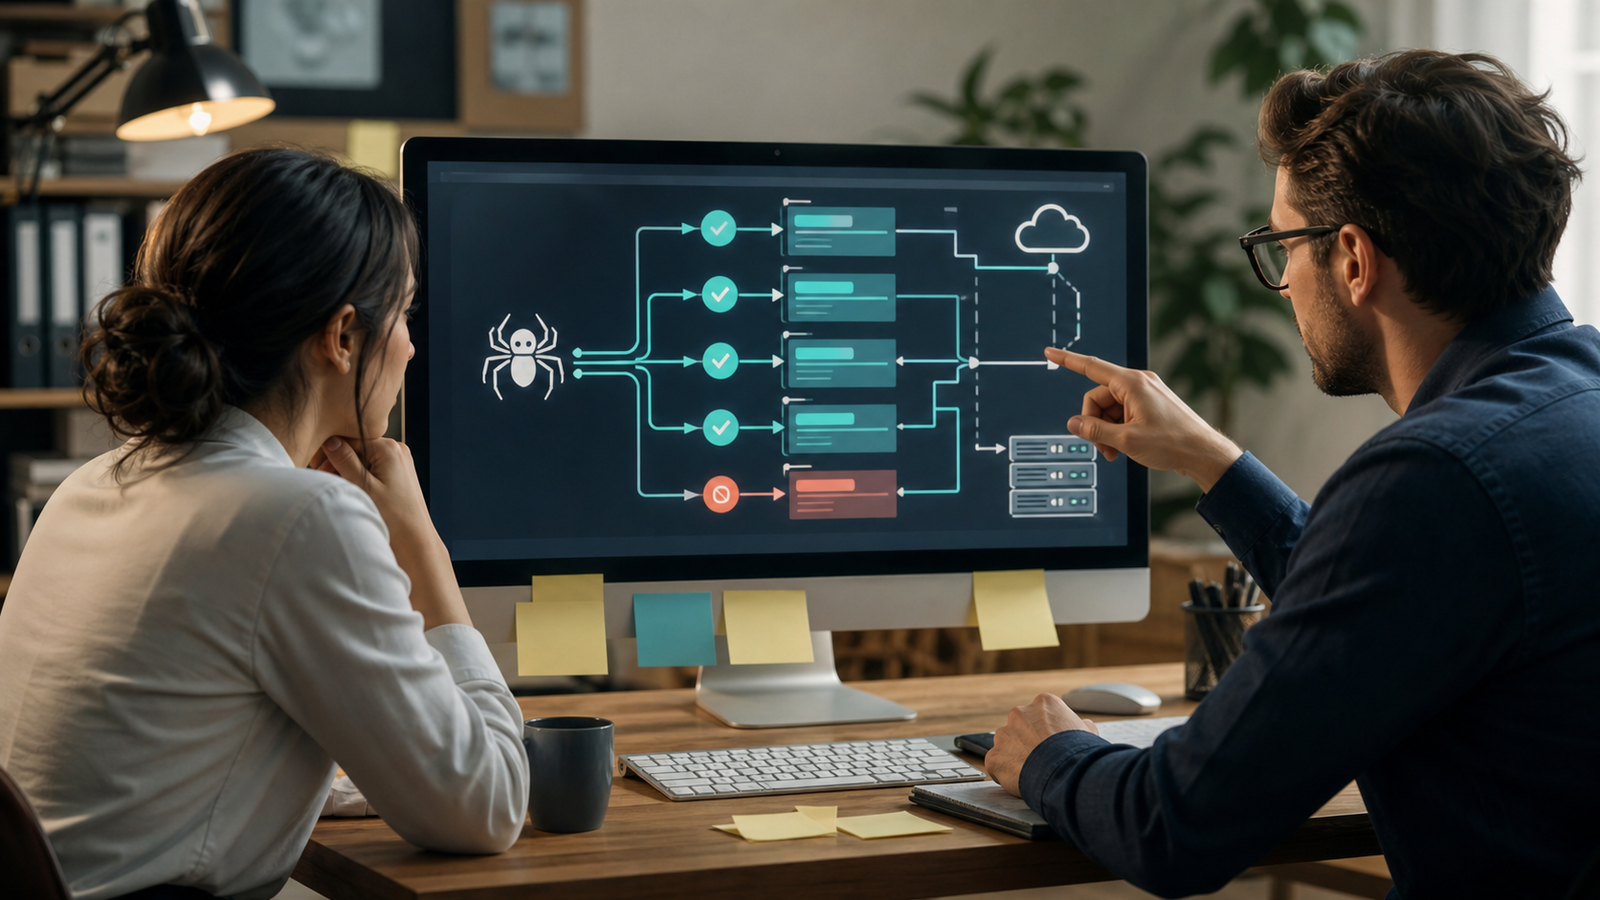
| Website area | Recommended default | Reason |
|---|---|---|
| Service pages, homepage, about page, contact page | Allow for search crawlers | These pages explain who you help, what you do, and how buyers can contact you. |
| Educational guides and FAQs | Allow if current and useful | These pages can support buyer questions and AI search citations when they contain clear answers and evidence. |
| Client portals, proposals, invoices, private PDFs | Protect with authentication | Robots.txt is not a security boundary. Private material should not be public. |
| Admin, account, cart, checkout, search result paths | Limit or block where appropriate | These areas usually do not help a buyer or AI system understand your services. |
| Training crawlers such as GPTBot | Decide separately | Training access is a business policy choice. It should not be bundled with search visibility by accident. |
CDN, firewall, and bot controls matter too
Many SMB sites use Cloudflare, security plugins, hosting firewalls, anti-spam tools, or managed WordPress protection. These tools can be useful, but they can also block legitimate crawlers if the settings are too broad.
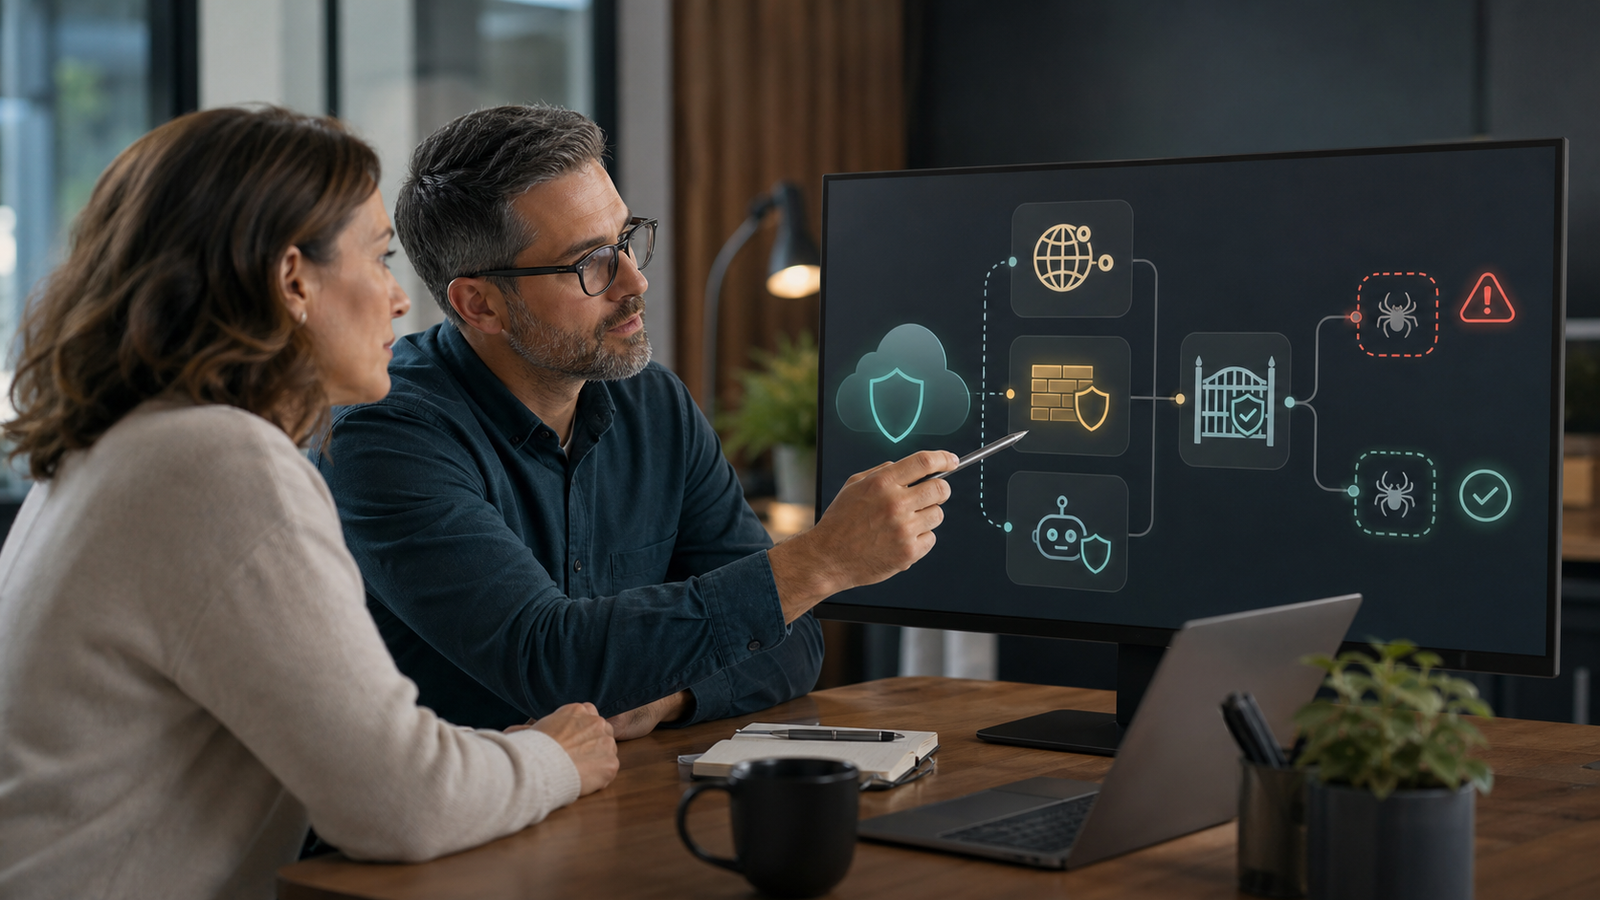
Cloudflare's AI Crawl Control documentation shows how site owners can review AI crawler activity and take crawler-specific actions. That is a different layer from robots.txt. If your site is behind a CDN or WAF, include those settings in the policy. Otherwise your robots file may say "allow" while the infrastructure returns 403, 429, a challenge page, or an empty response.
Infrastructure review checklist
- Confirm important public pages return HTTP 200 without login or challenge screens.
- Check whether the CDN, firewall, or security plugin blocks known AI crawlers.
- Review bot protection events after publishing a new policy.
- Watch for 403, 429, redirect loops, and JavaScript challenge pages.
- Keep IP allowlists current if your provider supports verified bot identity.
A concrete SMB example
Imagine a regional accounting firm that serves contractors and local service businesses. The firm wants to be visible when buyers ask AI tools about bookkeeping cleanup, monthly reporting, tax deadline preparation, and invoice workflow problems.
The firm's public pages should be crawlable: service pages, industry pages for contractors, an FAQ about monthly close, a practical guide to cleaning up receivables, and the contact page. These pages are useful source material. They explain the business and answer buyer questions.
But the same domain might also have old proposal PDFs in the media library, a client upload form, a staging page, and private intake forms. Those should not be handled with a casual Disallow line. They need removal, authentication, or a safer publishing pattern.
The policy for that firm could be simple: allow OAI-SearchBot and Googlebot on public marketing and education pages, decide GPTBot at the owner level, block or limit low-value CMS paths, protect client material with login, and review bot/security logs monthly for the first quarter after launch.
Monthly and quarterly monitoring
A crawler policy is not a set-and-forget file. Website sections change. Plugins change. Hosting protections change. AI crawler documentation changes. A policy that was sensible in January can become stale by August.
Use a light monitoring rhythm:
- Monthly: check key public URLs, Search Console coverage, server or CDN bot events where available, and whether AI search tools describe the business accurately.
- Quarterly: review robots.txt, sitemap URLs, public downloads, new forms, new landing pages, and training crawler decisions.
- After major website changes: repeat the crawler audit before assuming public pages are still reachable.
This is also where citeability comes back in. A page can be crawlable and still be weak source material. The related guide on making a website more citeable by AI search engines covers direct answers, evidence, examples, schema, and citation tests. Pair both checks: can the page be reached, and is it worth citing?
Mistakes to avoid
- Copying another site's robots.txt: their risk, CMS, commercial goals, and content strategy may be different.
- Blocking all AI crawlers without a visibility decision: that may reduce AI search discovery for public pages you actually want buyers to find.
- Using robots.txt as privacy protection: private material needs authentication or removal from public URLs.
- Forgetting CDN and firewall rules: infrastructure can block crawlers even when robots.txt allows them.
- Letting the policy age silently: new pages, lead magnets, downloads, and portals need review before they go live.
Want a practical crawler and AI search review?
If you are not sure whether your public pages are crawlable, citeable, and protected correctly, book an AI Search Visibility Audit. I will review crawler access, public-page clarity, source evidence, internal links, schema, and the next fixes that matter for your business.
Sources
- OpenAI, Overview of OpenAI CrawlersUsed for crawler roles, robots.txt tags, and the distinction between OAI-SearchBot, GPTBot, OAI-AdsBot, and ChatGPT-User.
- OpenAI Help Center, Advertiser Guidance for Allowing OpenAI Web CrawlersUsed for practical access layers such as robots.txt, web protection, bot mitigation, challenges, and rate limiting.
- Google Search Central, Introduction to robots.txtUsed for the point that robots.txt manages crawler access and is not a privacy mechanism.
- Google Search Central, AI Features and Your WebsiteUsed for Google AI feature eligibility and the continued importance of crawl access, internal links, textual content, and visible structured data.
- Cloudflare, Manage AI crawlersUsed for CDN-level AI crawler review, allow/block controls, and crawler activity monitoring.
- RFC 9309, Robots Exclusion ProtocolUsed for standards-level robots.txt behavior and the reminder that robots rules are not access authorization.
FAQ
Should a small business allow OAI-SearchBot?
If the business wants its public pages to be eligible for ChatGPT search visibility, allowing OAI-SearchBot is usually sensible. Still, public pages should be reviewed first so private or low-value material is not accidentally exposed.
Should GPTBot use the same rule as OAI-SearchBot?
Not automatically. OAI-SearchBot is tied to search visibility, while GPTBot is tied to training-related crawling. A business can allow one and disallow the other. The decision should be written into the policy.
Is robots.txt enough to protect private client documents?
No. Robots.txt is not a privacy or security tool. Private client material should require authentication, be removed from public URLs, or be published in a safer public format with sensitive details removed.
How often should an AI crawler policy be reviewed?
Review it quarterly and whenever the website adds a portal, resource library, new forms, public downloads, major service pages, or new security tooling. Also review it after crawler documentation or CDN settings change.
Can a crawler policy improve AI search visibility by itself?
It can remove a technical blocker, but it does not make a weak page citeable. Public pages still need clear service information, direct answers, examples, internal links, credible sources, schema that matches visible content, and a useful next step.
